

Neljä johtavaa mallia. Yhdeksän kategoriaa. Yksi kokonaisvoittaja. Tämä ei ole laboratoriomittaus hämärine pistetaulukkoineen. Kyse on käytännön, päästä-päähän -vertailusta, joka perustuu tehtäviin, joista ihmiset oikeasti välittävät: todellisten ongelmien ratkaiseminen aikapaineessa, kuvien ja videoiden generointi, faktantarkistus ilman internetiä, sotkuisten syötteiden analysointi, luovuus vaatimuksesta, luonnollinen puhe ja perusteellinen tutkimus, joka kestää tarkastelua. Arvioimme jokaisen alatehtävän asteikolla 0–4 ja pidimme juoksevaa pistelaskua. Lopuksi kruunasimme mestarin ja, mikä tärkeämpää, kartoimme jokaisen mallin vahvimmat käyttötapaukset.
Kärkeen heti: Gemini voittaa kokonaispistein 46. ChatGPT sijoittuu tiukasti kakkoseksi 39 pisteellä. Grok on kolmas 35 pisteellä. DeepSeek jää jälkeen 17 pisteellä. Tämä ei tarkoita, että voittajaa pitäisi valita aina — eri kategoriat suosivat eri vahvuuksia, ja oikea malli riippuu siitä työstä, jonka haluat tehdä. Tässä arviossa näytetään täsmällisesti missä kukin malli loistaa ja missä se kompastelee, konkreettisin esimerkein ja täysin läpinäkyvällä pisteytyksellä.
How We Tested
Models compared: ChatGPT, Gemini, Grok, DeepSeek.
Categories: nine in total. Some include multiple rounds or prompts.
Scoring: each round is graded 0–4. Where the source comparison specified explicit scores or rank orders, we used those; otherwise we followed the same rules and rubric.
Constraints: when a round forbid internet access, we honored that constraint. Where a capability does not exist (for example, image or video generation in DeepSeek), the model scores zero for that round.
Speed: recorded descriptively, not scored as its own category, to keep totals aligned with the original contest.
Tavoitteemme ei ollut laatia koukeroisia kysymyksiä. Halusimme tutkia todellisen maailman käyttäytymistä, mukaan lukien epäonnistumismuodot kuten keksityt yksityiskohdat kuva-analyysissä tai pinnallinen budjettilaskenta, joka sivuuttaa annetun tilanteen.
Category 1: Problem Solving
Kaksi realistista haastetta. Arvioidaan erikseen ja lasketaan yhteen.
Round 1: You have 10 dollars, a dead phone, no map, and 45 minutes to reach a central train station in a foreign city. Give a five-step plan.
Speed: DeepSeek replies in 7 seconds, Grok in 11, Gemini in 21, ChatGPT in 62.
Quality: all four deliver structured, workable five-step plans.
Peer review twist: we then showed all four answers to each model and asked them to pick the best. Every model independently selected ChatGPT’s answer.
Scores, Round 1
ChatGPT 4, Gemini 3, Grok 2, DeepSeek 1.
Round 2: You have 400 dollars after rent to cover groceries, transport, and internet. Groceries cost 50 per week, transport 80 per month, internet 60 per month. You want to attend a 200 dollar event next month. How do you budget?
Ajattelun ansa. ChatGPT, Grok ja DeepSeek päätyvät säästämään vain 60 dollaria nyt ja ”säästämään lisää ensi kuussa”, mikä on liian myöhäistä. Gemini on ainoa malli, joka muuttaa suunnitelmaa välittömästi: vähennä ruokakuluja 15 dollaria viikossa etsimällä alennuksia ja noudattamalla tiukkaa ateriasuunnittelua, jolloin puute korjataan tässä kuussa.
Scores, Round 2
Gemini 4, ChatGPT 3, Grok 3, DeepSeek 2.
Problem Solving Totals
| Model | Round 1 | Round 2 | Total |
|---|---|---|---|
| ChatGPT | 4 | 3 | 7 |
| Gemini | 3 | 4 | 7 |
| Grok | 2 | 3 | 5 |
| DeepSeek | 1 | 2 | 3 |
Tulkinta: ChatGPT osoittaa vahvaa vaiheittaista suunnittelua ja voittaa vertaisarvioäänen; Gemini osoittaa parempaa sopeutumiskykyä rajoitteiden alla. Molemmat sijoittuvat ensimmäiseksi kokonaispistein.
Category 2: Image Generation
Kaksi kehotetta. DeepSeek ei voi generoida kuvia ja saa nollan oletuksena.
Prompt 1: Photoreal Mona Lisa as a frustrated street protester in Times Square, holding a cardboard sign that reads “Make Florence great again” in bold red letters.
Grok: fastest, but obviously artificial. The subject looks wrong, even with extra hands.

Gemini: good composition and setting; the subject still has three hands.
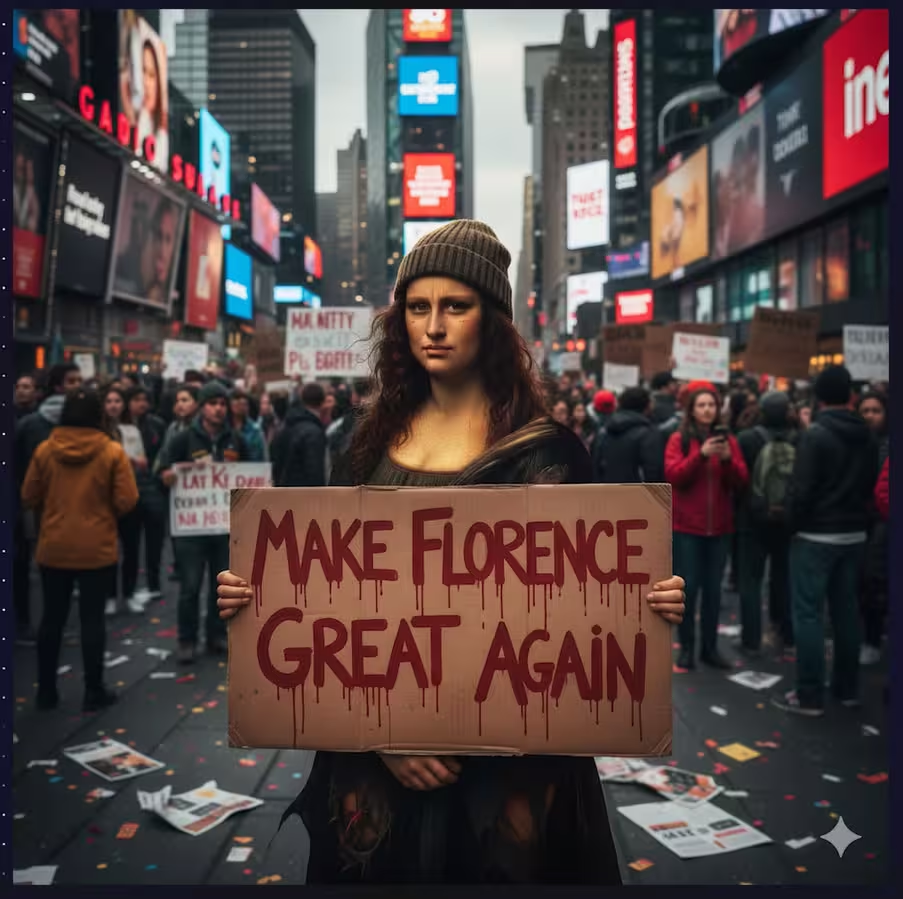
ChatGPT: most natural subject with a convincing Times Square background; the sign and pose match the brief.

Scores
ChatGPT 4, Gemini 3, Grok 1, DeepSeek 0.
Prompt 2: Photoreal classroom with a hippie-style teacher beside a chalkboard showing the full alphabet in chalk, letters decreasing in size.
Grok: classroom and handwriting feel authentic, but the alphabet itself is wrong and incomplete.
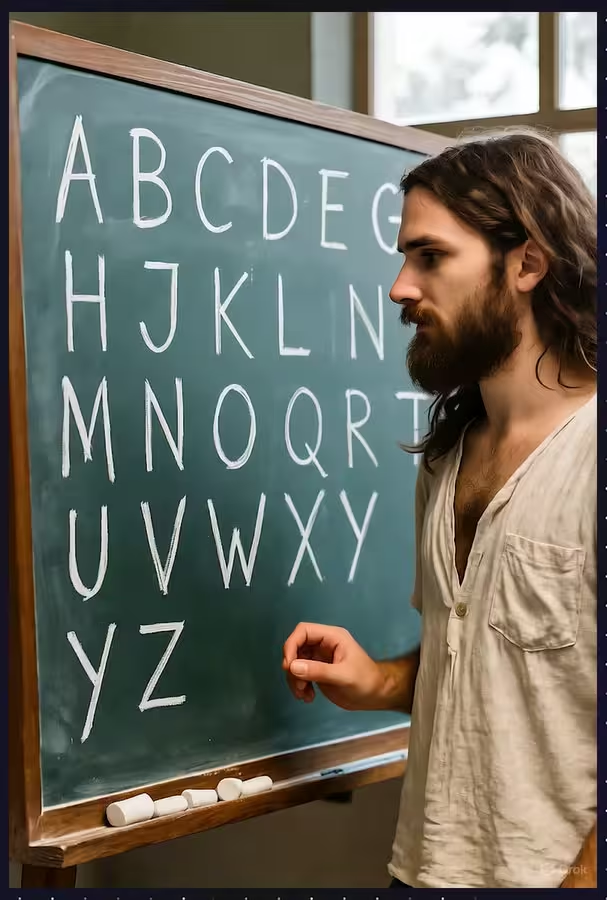
Gemini: aesthetically pleasing, but more stylized than photoreal; extraneous, too-perfect lettering.

ChatGPT: most convincing overall; lighting, classroom details, and teacher are credible. Handwriting is arguably too perfect.

The original contest capped the top score at 3 for this specific round.
Scores
ChatGPT 3, Gemini 2, Grok 2, DeepSeek 0.
Image Generation Totals
| Model | P1 | P2 | Total |
|---|---|---|---|
| ChatGPT | 4 | 3 | 7 |
| Gemini | 3 | 2 | 5 |
| Grok | 1 | 2 | 4 |
| DeepSeek | 0 | 0 | 0 |
Tulkinta: ChatGPT on luotettavin valokuvauskaltaisiin pyyntöihin. Gemini pääsee yleensä lähelle, kun taas Grok kamppailee hienojen anatomisten yksityiskohtien ja tekstin paikkansapitävyyden kanssa.
Category 3: Fact-Checking Without Internet
Kolme monivalintakysymystä. Luottamusarvot kirjattiin, mutta ne eivät vaikuttaneet rubriikkaan.
Q1: In 2018, about how many chickens were killed for meat production?
Options: 690 million, 6.9 billion, 69 billion, 690 billion.
Correct: 69 billion.
Grok answers 69 billion outright.
ChatGPT gives a range that includes the right figure.
Gemini and DeepSeek cluster lower around 65 billion.
Scores
Grok 4, ChatGPT 3, Gemini 1, DeepSeek 1.
Q2: As of 2020, approximately how much annual income puts you in the richest 1 percent globally?
Options: 200k, 75k, 35k, 15k.
Correct: 35k.
Gemini states 34k.
ChatGPT 200k, Grok 60k, DeepSeek 75–85k.
Scores
Gemini 4, others 0.
Q3: In 2019, what proportion of U.S. electricity came from fossil fuels?
Options: 83%, 63%, 43%, 23%.
Correct: 63%.
Gemini hits 63% exactly.
ChatGPT 63–65%, Grok 62%, DeepSeek 60–65%.
Scores
Gemini 4, ChatGPT 3, Grok 3, DeepSeek 3.
Fact-Checking Totals
| Model | Q1 | Q2 | Q3 | Total |
|---|---|---|---|---|
| ChatGPT | 3 | 0 | 3 | 6 |
| Gemini | 1 | 4 | 4 | 9 |
| Grok | 4 | 0 | 3 | 7 |
| DeepSeek | 1 | 0 | 3 | 4 |
Tulkinta: Gemini voittaa tarkkuudessa ja johdonmukaisuudessa. Grok osuu ensimmäiseen kysymykseen, mutta epäonnistuu tulotasoa koskevassa arvioinnissa. ChatGPT:n vaihteluvälit auttavat, mutta täsmällisyys on ratkaisevaa.
Category 4: Multimodal Analysis
Kaksi kierrosta: jääkaappikuva ja Where’s Waldo -tyylinen kohtaus.

Round 1: What’s in the fridge, and propose three meals from those ingredients.
DeepSeek cannot identify objects and is out.
ChatGPT misses three items, does not invent extras, proposes reasonable meals that match the inventory.
Gemini misses seven items and invents citrus that does not exist.
Grok misses three but invents a long list of additional items, then writes recipes that require those phantom ingredients.

Scores
ChatGPT 4, Gemini 3, Grok 2, DeepSeek 0.
Round 2: Find Waldo in a busy illustration.

Kukaan malleista ei löydä Waldoa oikein. DeepSeek lukeutuu hajanaista tekstiä eikä tarjoa varsinaista vastausta.
Scores
All 0.
Analysis Totals
| Model | Fridge | Waldo | Total |
|---|---|---|---|
| ChatGPT | 4 | 0 | 4 |
| Gemini | 3 | 0 | 3 |
| Grok | 2 | 0 | 2 |
| DeepSeek | 0 | 0 | 0 |
Tulkinta: keksityt kohteet ovat tuhoisia käytännön hyödyllisyyden kannalta. ChatGPT vastustaa keksimisen kiusausta, ja tämä pidättyvyys voittaa kierroksen.
Category 5: Video Generation
Kaksi klassista kohtausta. DeepSeek ei pysty generoimaan videoita ja saa nollan.
Round 1: Image-to-video from the iconic photo of Neil Armstrong on the Moon

Sora 2 kieltäytyi animaatiosta suoraan ihmisistä, joten uudelleenkehotimme tekstikuvauksella. Äänitulokset olivat yllättävän vahvoja.
Gemini: most cinematic feel and best audio alignment. Physics slip: the flag waves, which cannot happen in a vacuum.
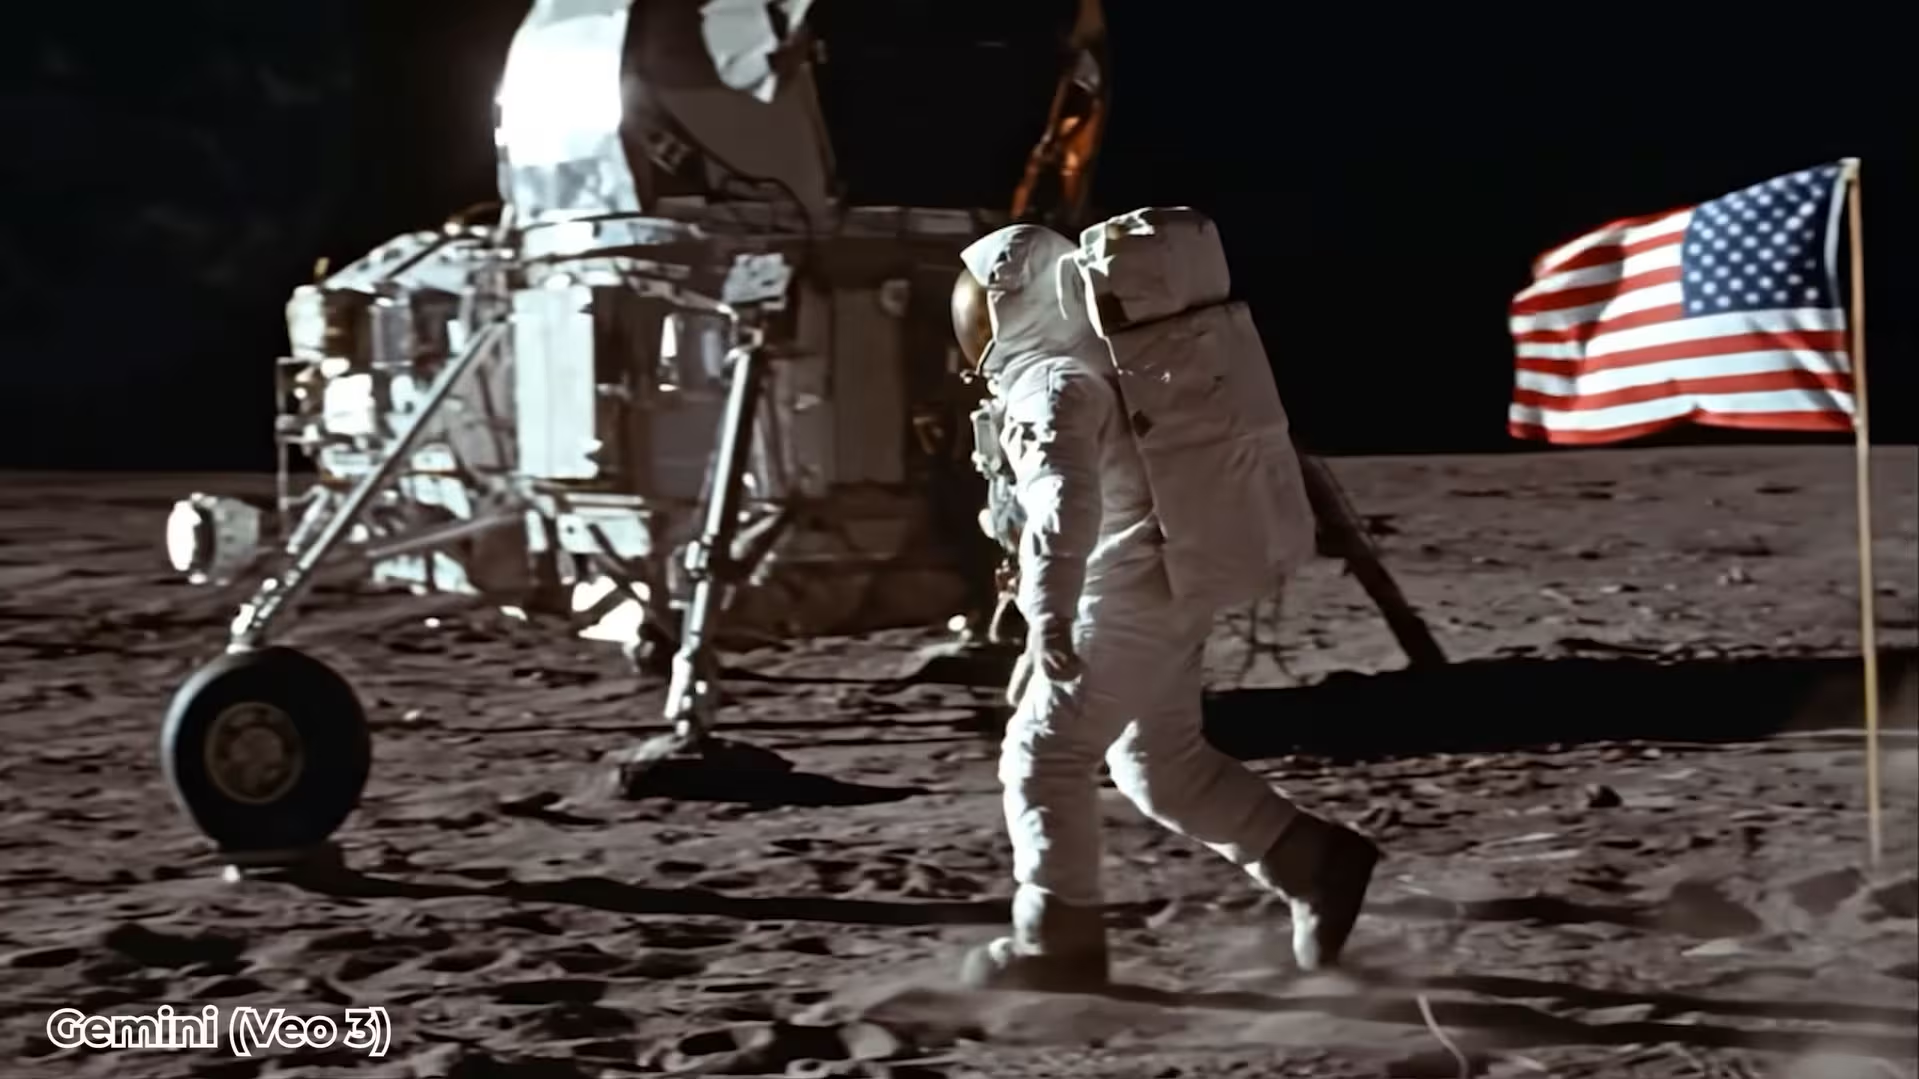
Grok: solid overall, but ship scale is off and there is wind.

ChatGPT: acceptable but less compelling than the other two.

Scores
Gemini 4, Grok 3, ChatGPT 2, DeepSeek 0.
Round 2: Steel-beam workers high above the city
Gemini: best camera movement and parallax; cigarettes look slightly off.

Grok: strong tension with the swinging beam; newspapers morph unrealistically mid-scene.
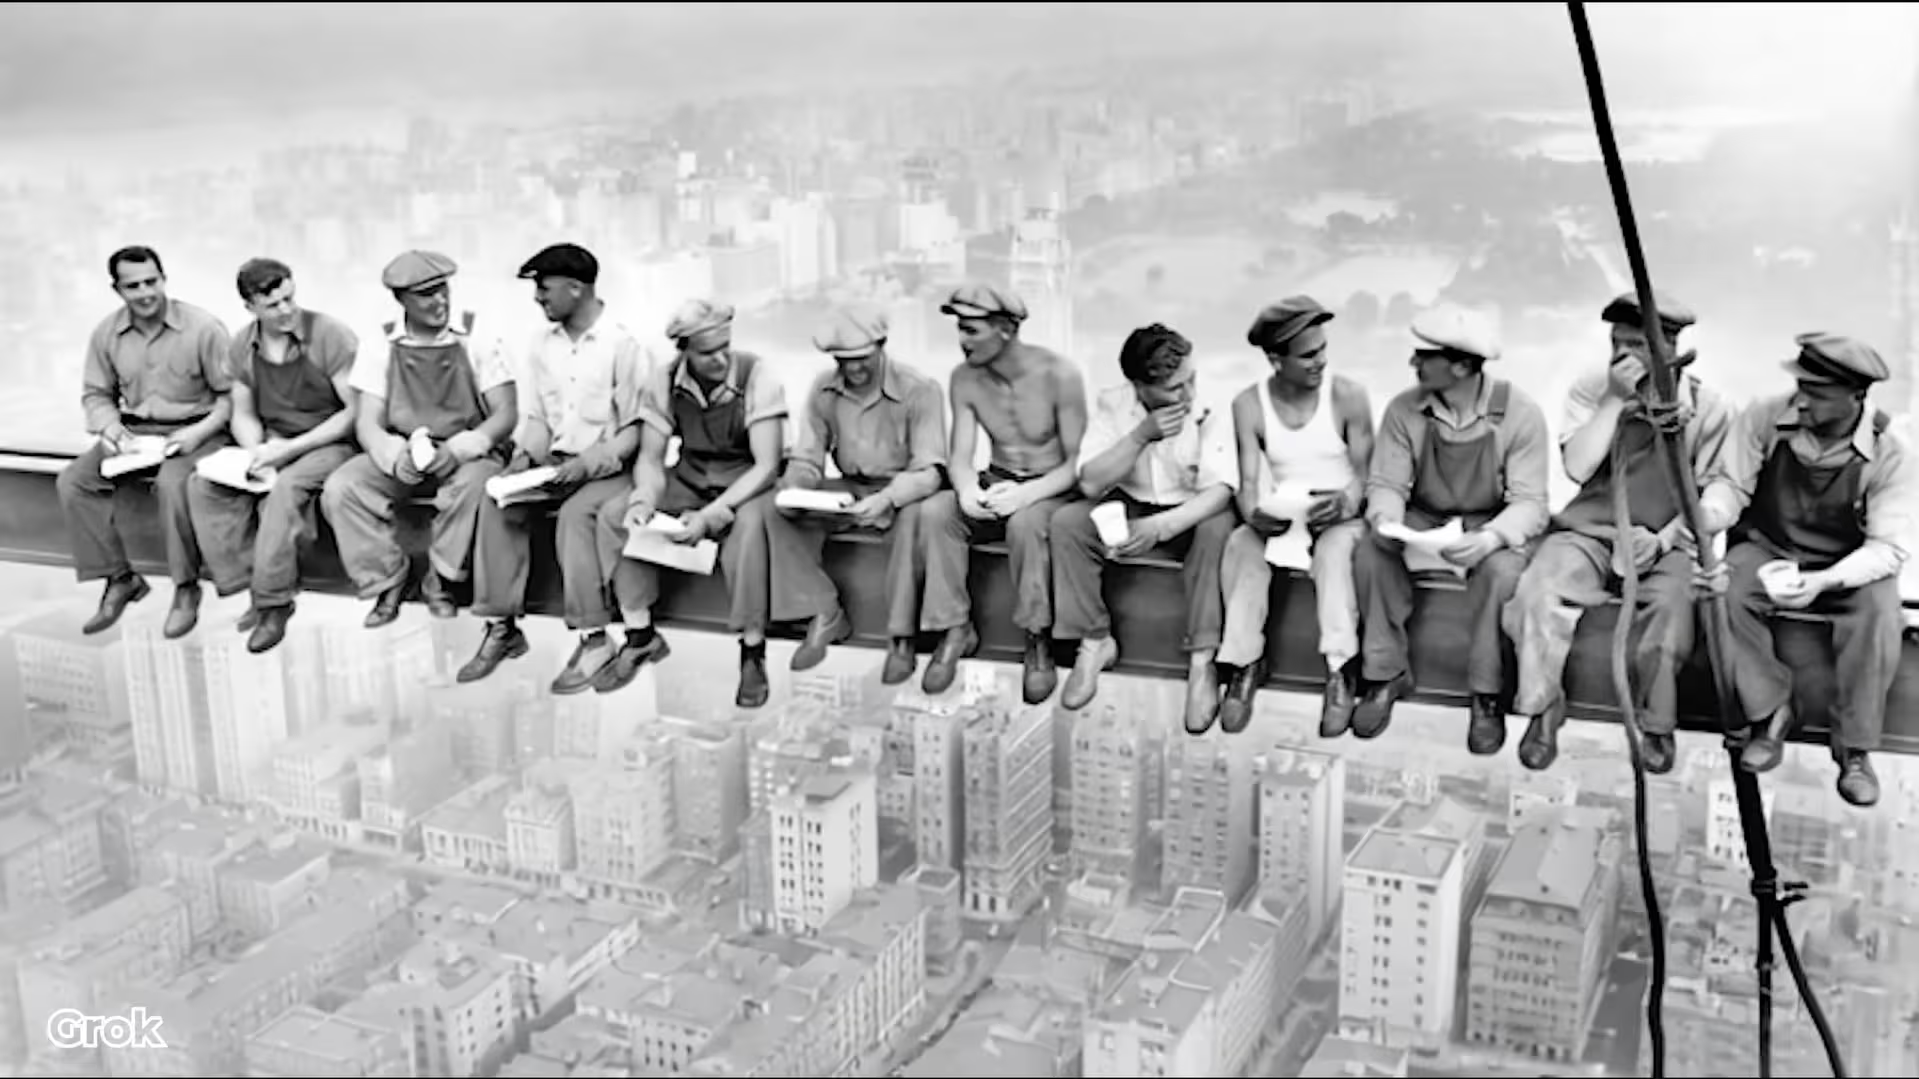
ChatGPT: decent but not at the top.

Scores
Gemini 4, Grok 3, ChatGPT 2, DeepSeek 0.
Video Generation Totals
| Model | R1 | R2 | Total |
|---|---|---|---|
| Gemini | 4 | 4 | 8 |
| Grok | 3 | 3 | 6 |
| ChatGPT | 2 | 2 | 4 |
| DeepSeek | 0 | 0 | 0 |
Tulkinta: Gemini johtaa selvästi liikkeen laadussa ja äänisuunnittelussa. Grok on lähellä mutta tekee realismivirheitä. ChatGPT on tasainen, mutta vähemmän elokuvallinen.
Category 6: Creative Generation
Kaksi lyhyttä kehotetta sanaleikeille ja isävitseille.
Prompt 1: Three original tech puns and a one-sentence explanation for each
Kaikki neljä noudattavat ohjetta siististi. Tiimin suosikki:
”Yritin tehdä vitsin USB:istä, mutta se ei vain tarttunut.”
Scores
ChatGPT 3, Gemini 3, Grok 3, DeepSeek 3.
Prompt 2: Three original dad jokes that make me laugh really hard
Grok fails to follow the general prompt and keeps joking about smartphones and Wi-Fi.
ChatGPT, Gemini, DeepSeek deliver actual general dad jokes. Team favorite:
”Kaverini leipomo paloi viime yönä. Nyt hänen bisneksensä on toast.”
Scores
ChatGPT 4, Gemini 4, DeepSeek 4, Grok 1.
Creative Totals
| Model | Puns | Dad Jokes | Total |
|---|---|---|---|
| ChatGPT | 3 | 4 | 7 |
| Gemini | 3 | 4 | 7 |
| DeepSeek | 3 | 4 | 7 |
| Grok | 3 | 1 | 4 |
Tulkinta: kolmen tahon tasapeli kärkisijasta. DeepSeek muistuttaa, että kevyt ja nopea huumori on yksi sen eloisimmista vahvuuksista.
Category 7: Voice Mode
Asetimme kolme laitetta vierekkäin ja pidimme rakenteellisia miniväittelyjä. DeepSeekillä ei ole äänitilaa ja sille merkitään nolla.
ChatGPT starts with odd pauses and mid-sentence tone shifts.
Gemini is smoother and more natural, with a consistent rhythm.
Grok is fast, confident, and a bit spicy; in a head-to-head with Gemini, both sound strong and we call it a tie.
Scores
Gemini 4, Grok 4, ChatGPT 2, DeepSeek 0.
Tulkinta: jos haluat luonnollisen äänikeskustelun, Gemini ja Grok ovat parhaat valinnat tällä hetkellä.
Category 8: Deep Research
Prompt: compare iPhone 17 Pro Max vs Galaxy S25 Ultra for photographers, use reviews and official specs, decide which is better, be concise.
DeepSeek incorrectly claims a 5x telephoto on iPhone where it is 4x, and misstates the Galaxy ultrawide as 12 MP instead of 50; keeps referencing a 10x tele lens dropped since S24.
ChatGPT forgets the dual tele setup on Galaxy and omits front cameras, but does include price.
Gemini lists the correct Galaxy camera array and produces a balanced conclusion.
Grok gives the most complete and accurate spec walkthrough.

Kaikki neljä yhtyvät samaan johtopäätökseen: iPhone voittaa johdonmukaisuudessa ja videolaadussa; Galaxy hallitsee pitkän zoomin ja edistyneet tekoälytyökalut. Tämä vastaa käytännön kokemuksia. Silti yksittäiset tekniset tiedot pitää varmistaa erikseen.
Scores
Grok 4, Gemini 3, ChatGPT 2, DeepSeek 1.
Tulkinta: Grok vie voiton tutkimustyössä, Gemini on lähellä, ChatGPT on käyttökelpoinen mutta jätti keskeisiä kamerapisteitä mainitsematta, DeepSeek tarvitsee tarkempaa lähestymistä teknisiin tietoihin.
Category 9: Speed (Observed, Not Scored)
ChatGPT feels fastest on plain text but slows on image and deep research tasks.
Gemini is steady almost everywhere; rarely the very fastest, almost never the slowest.
Grok is generally snappy but can bog down in analysis and research.
DeepSeek often responds in under 10 seconds, but that speed frequently trades away context and accuracy.
Emme arvioineet nopeutta omana kategorianaan, jotta pisteet pysyvät yhteneväisinä alkuperäisen kilpailun tulosten kanssa.
Full Scoreboard
For transparency, here is the complete table of points by category, matching the source competition’s final tallies.
| Category | ChatGPT | Gemini | Grok | DeepSeek |
|---|---|---|---|---|
| Problem Solving | 7 | 7 | 5 | 3 |
| Image Generation | 7 | 5 | 4 | 0 |
| Fact-Checking | 6 | 9 | 7 | 4 |
| Analysis | 4 | 3 | 2 | 0 |
| Video Generation | 4 | 8 | 6 | 0 |
| Creative | 7 | 7 | 4 | 7 |
| Voice Mode | 2 | 4 | 4 | 0 |
| Deep Research | 2 | 3 | 4 | 1 |
| Total | 39 | 46 | 35 | 17 |
Overall winner: Gemini (46 points).
Runner-up: ChatGPT (39). Third place: Grok (35). Fourth place: DeepSeek (17).
Strengths, Weaknesses, and Failure Modes
A head-to-head only helps if it explains why models behave the way they do. These are the consistent patterns we observed.
ChatGPT
Strengths: highly structured reasoning under constraints; conservative, less hallucinatory image analysis; unusually strong photoreal image generation; reliable, punchy creative writing.
Weaknesses: slows down on heavyweight multimodal tasks; occasional spec omissions in research; voice delivery needs more prosody stability.
Failure modes to watch: small but important factual gaps in multi-device comparisons; under-specced answers if the prompt is too concise.
Pick ChatGPT if: you need image generation that obeys prompts, stepwise plans, or creative copy that lands cleanly and consistently. It is also great for food and recipe logic when inventory is imperfect.
Gemini
Strengths: best overall balance; sharp at fact-checking without internet; most convincing video output and audio staging; problem-solving that adapts the plan rather than waving at the math; smoothest voice.
Weaknesses: occasional over-polish in images; can add neat but imaginary details in visual analysis; rarely the absolute fastest.
Failure modes to watch: photoreal prompts that demand painstaking typography or human anatomy perfection can trip it; be explicit about constraints like physics in video.
Pick Gemini if: you want a default model that handles most tasks very well, especially when the work blends reasoning with multimodal generation and you care about correctness.
Grok
Strengths: excellent deep research; punchy personality in voice; quick first passes; strong understanding of debate structure.
Weaknesses: image hallucinations during visual analysis; realism breaks in video; occasional tunnel vision in creative prompts.
Failure modes to watch: invented items in photos; confident but wrong specifics; sticking to a discarded theme when the prompt has changed.
Pick Grok if: you need a sharp research aide to consolidate specs and reviews, or a lively voice presence. Pair with manual verification when precision matters.
DeepSeek
Strengths: fast on text; surprisingly solid at light, short-form humor; decent at following simple creative briefs.
Weaknesses: no image or video generation; cannot identify objects in images; looser factual grip in research.
Failure modes to watch: confident but skewed numbers; reading text inside images while ignoring the scene.
Pick DeepSeek if: you want inexpensive, very fast text output for simple tasks, jokes, or drafts where you plan to edit anyway.
Practical Recommendations by Use Case
Photoreal image generation with strong prompt adherence: ChatGPT
Image analysis without hallucinated objects: ChatGPT
Video generation with better motion and sound design: Gemini
Tough fact-checking without browsing: Gemini
Problem solving under constraints: Gemini and ChatGPT
Natural, steady voice conversation: Gemini and Grok
Spec comparisons and product research summaries: Grok
Quick, lightweight creative text: DeepSeek
Why the Winner Matters Less Than the Fit
Gemini sai korkeimman pistemäärän, koska se yhdistää tarkkuuden, sopeutumiskyvyn ja multimodaalisen laadun. Tämä tasapaino voittaa kilpailuja. Todellisessa työssä ratkaisee kuitenkin soveltuvuus tehtävään. Jos työsi pyörii staattisten kuvien ympärillä, ChatGPT voi pärjätä paremmin kuin pisteet antavat ymmärtää. Jos koostat teknisiä taulukoita, Grok voi olla nopein tie julkaistavaan luonnokseen. Jos tarvitset halvan, nopean vitsin tai raakaluonnoksen, DeepSeekin nopeus on ominaisuus, ei virhe.
Ajattele näitä malleja kameran objektiiveina. ”Paras” objektiivi paperilla ei ole aina se, jota tarvitset. Valitse polttoväli, joka sopii otokseen.
Limitations and Notes on Reproducibility
No internet rounds: all models worked from embedded knowledge, which ages. If you repeat these tests months later, fact numbers may drift as model snapshots or training data refresh.
Generative variability: run-to-run randomness can change the exact wording or small details. We controlled for this by focusing on correctness and adherence, not phrasing flair.
Speed: recorded qualitatively. Infrastructure and load influence latency; today’s fastest model might feel slower tomorrow.
Modal gaps: where a capability does not exist (DeepSeek for images and video), a zero is not a knock on text ability. It simply reflects product scope.
Verdict
Winner: Gemini (46 points). Best all-around for 2025, with standout results in fact-checking, video generation, and adaptive problem solving, plus the smoothest voice.
Runner-up: ChatGPT (39 points). Photoreal image leader, structured problem solver, dependable creative partner, and the most careful on image-based analysis.
Third: Grok (35 points). Research ace with a distinctive voice personality. Verify specifics when precision is critical.
Fourth: DeepSeek (17 points). Fast, simple, and unexpectedly fun for lightweight creative, but lacks the multimodal depth of rivals.
If you want one model that handles the broadest span of everyday tasks with the fewest surprises, pick Gemini. If your workflow leans on images and you value careful, stepwise reasoning, ChatGPT will feel like home. For spec-heavy briefs and pithy spoken debates, Grok is compelling. For rapid, low-stakes text where cost and speed matter more than breadth, DeepSeek earns its keep.
Nine categories. One scoreboard. Plenty of room for nuance. Choose the right tool, and any of these models can be the smartest teammate in the room.

"Minua kiehtoo mobiililaitteet ja älypuhelimien kehitys. Kirjoitan artikkeleita uusista laitteista, testeistä ja käyttäjäkokemuksista."
Keskustelu
Jätä kommentti
Kommentit
Ei vielä kommentteja. Ole ensimmäinen.